Agentic Retrieval: The Complete Guide from Document Ingestion to Compiled Knowledge
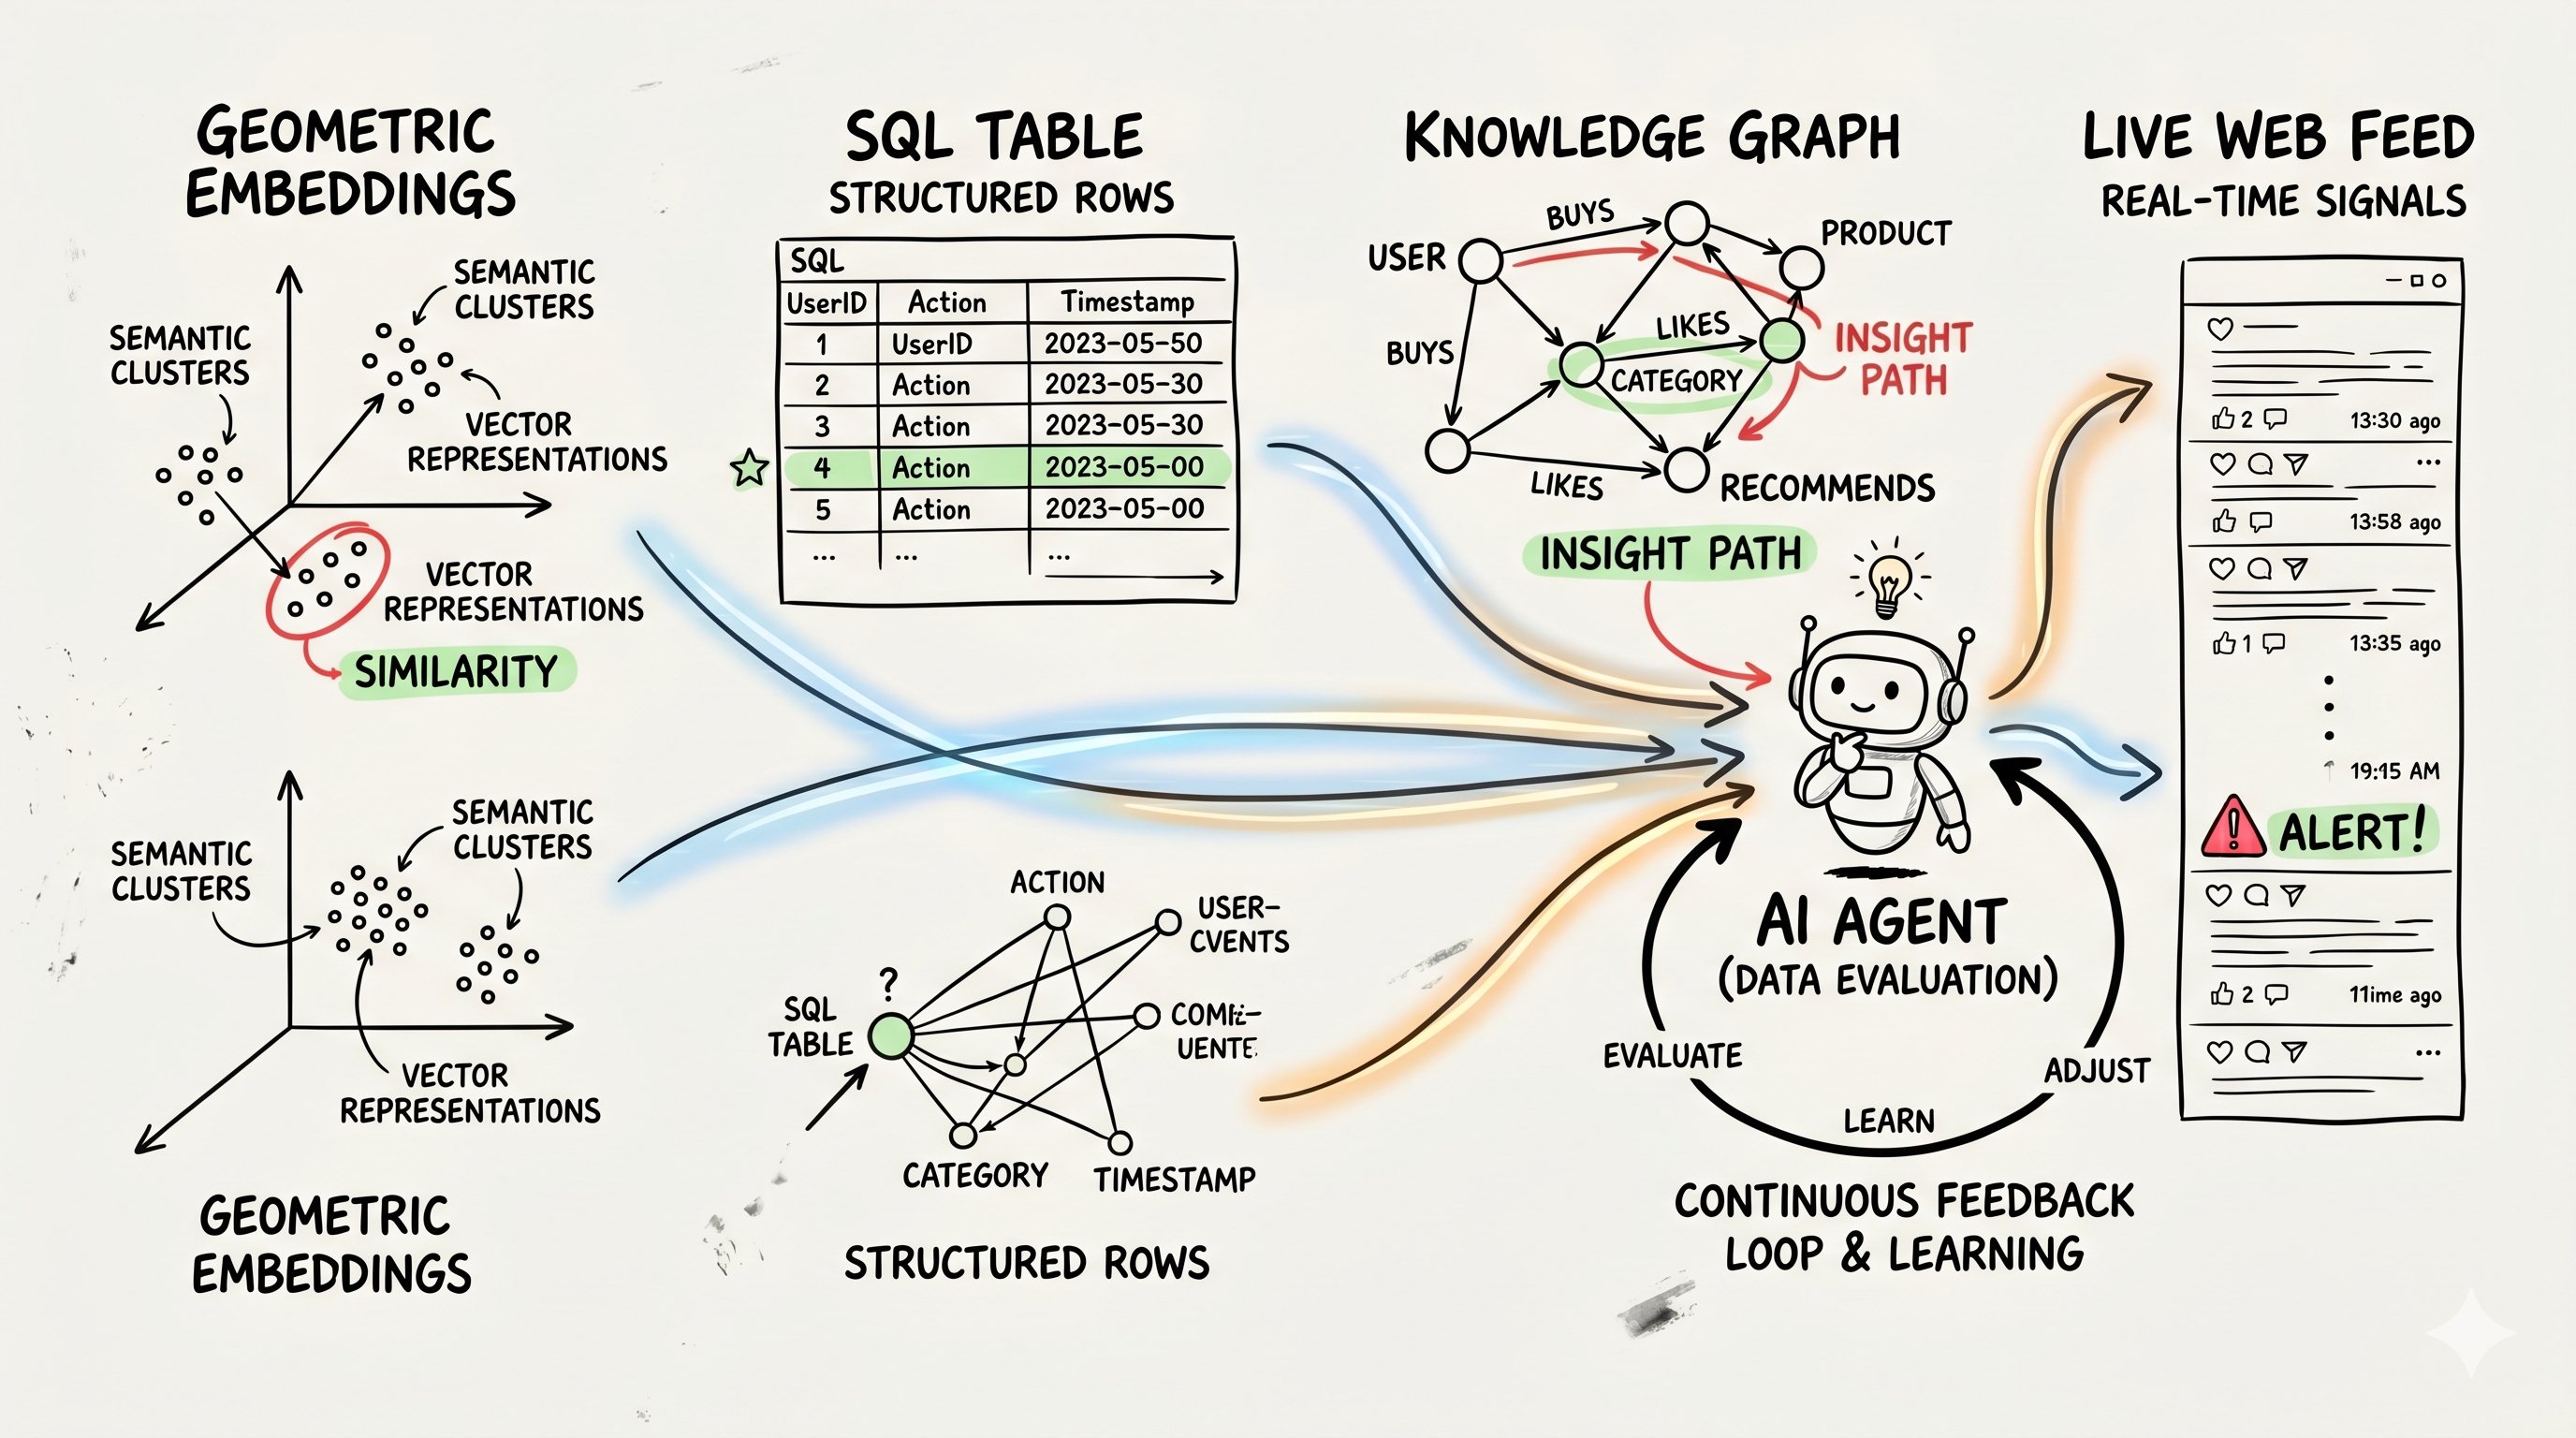
Naive RAG fails roughly 40% of the time at retrieval. Not because the LLM is bad — because what you hand it is bad. Wrong chunks, missing context, no awareness of what it doesn't know. Agentic retrieval fixes the retrieval layer, not the generation layer.
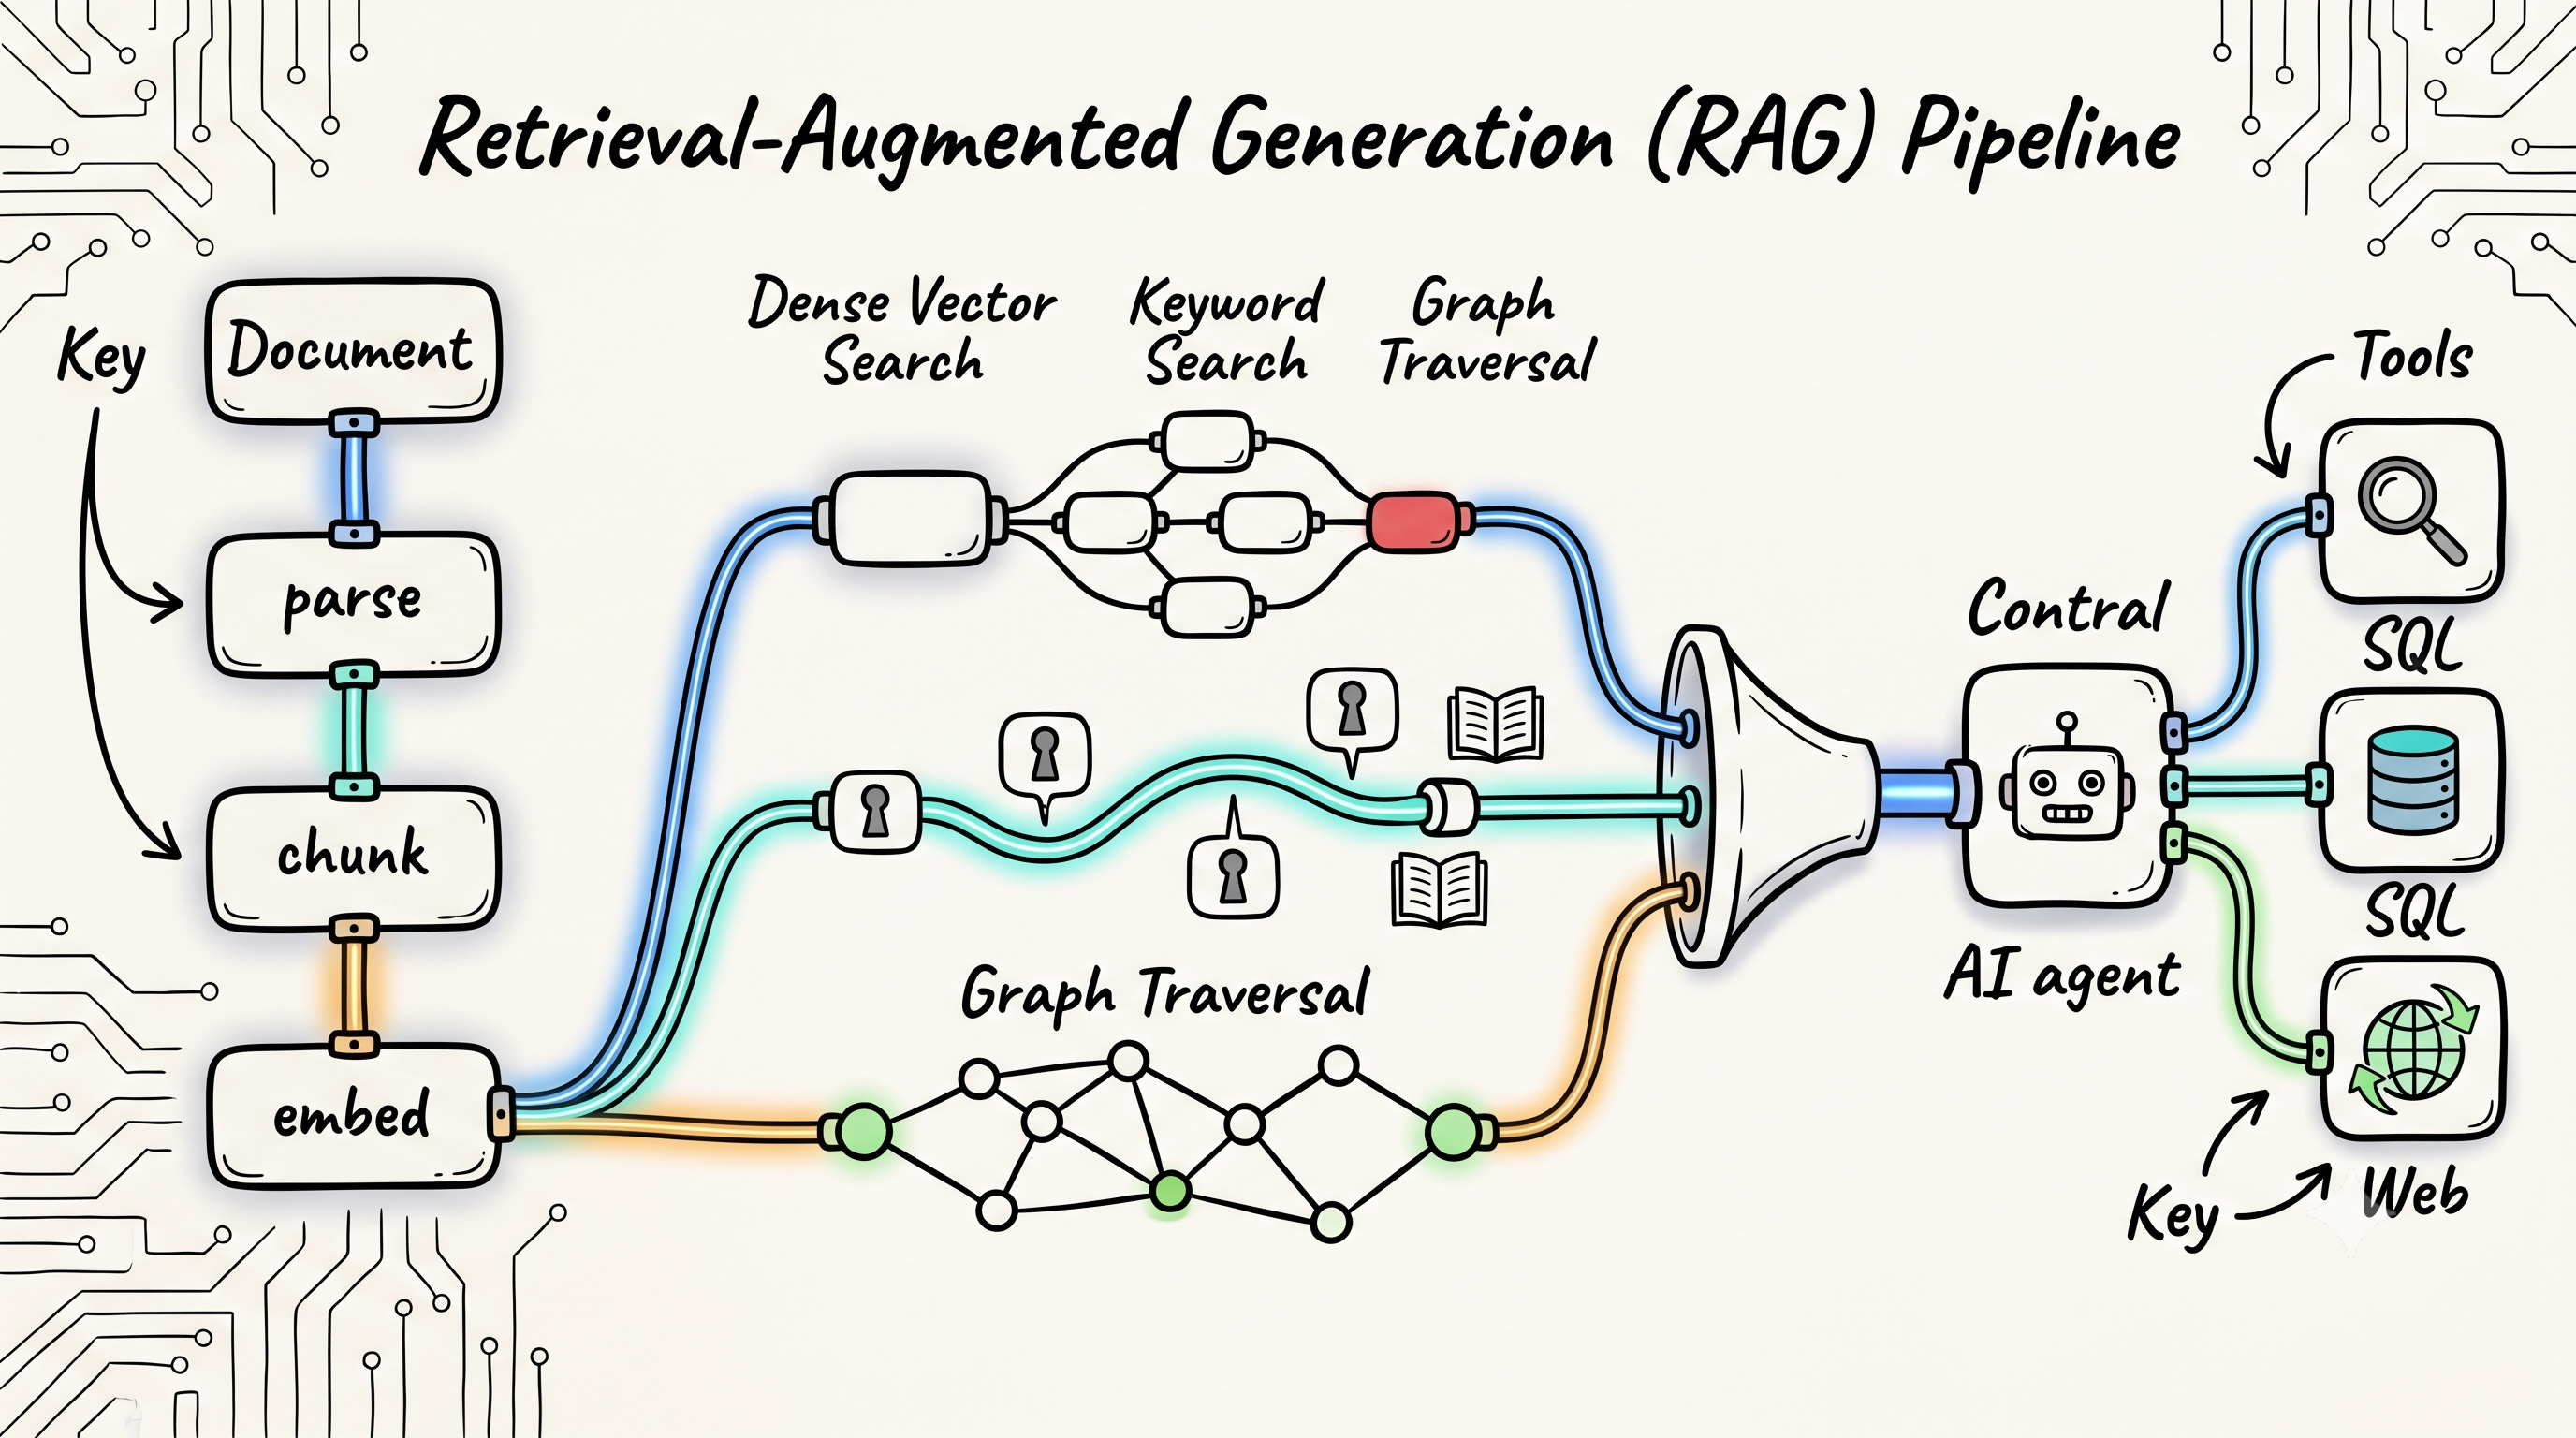
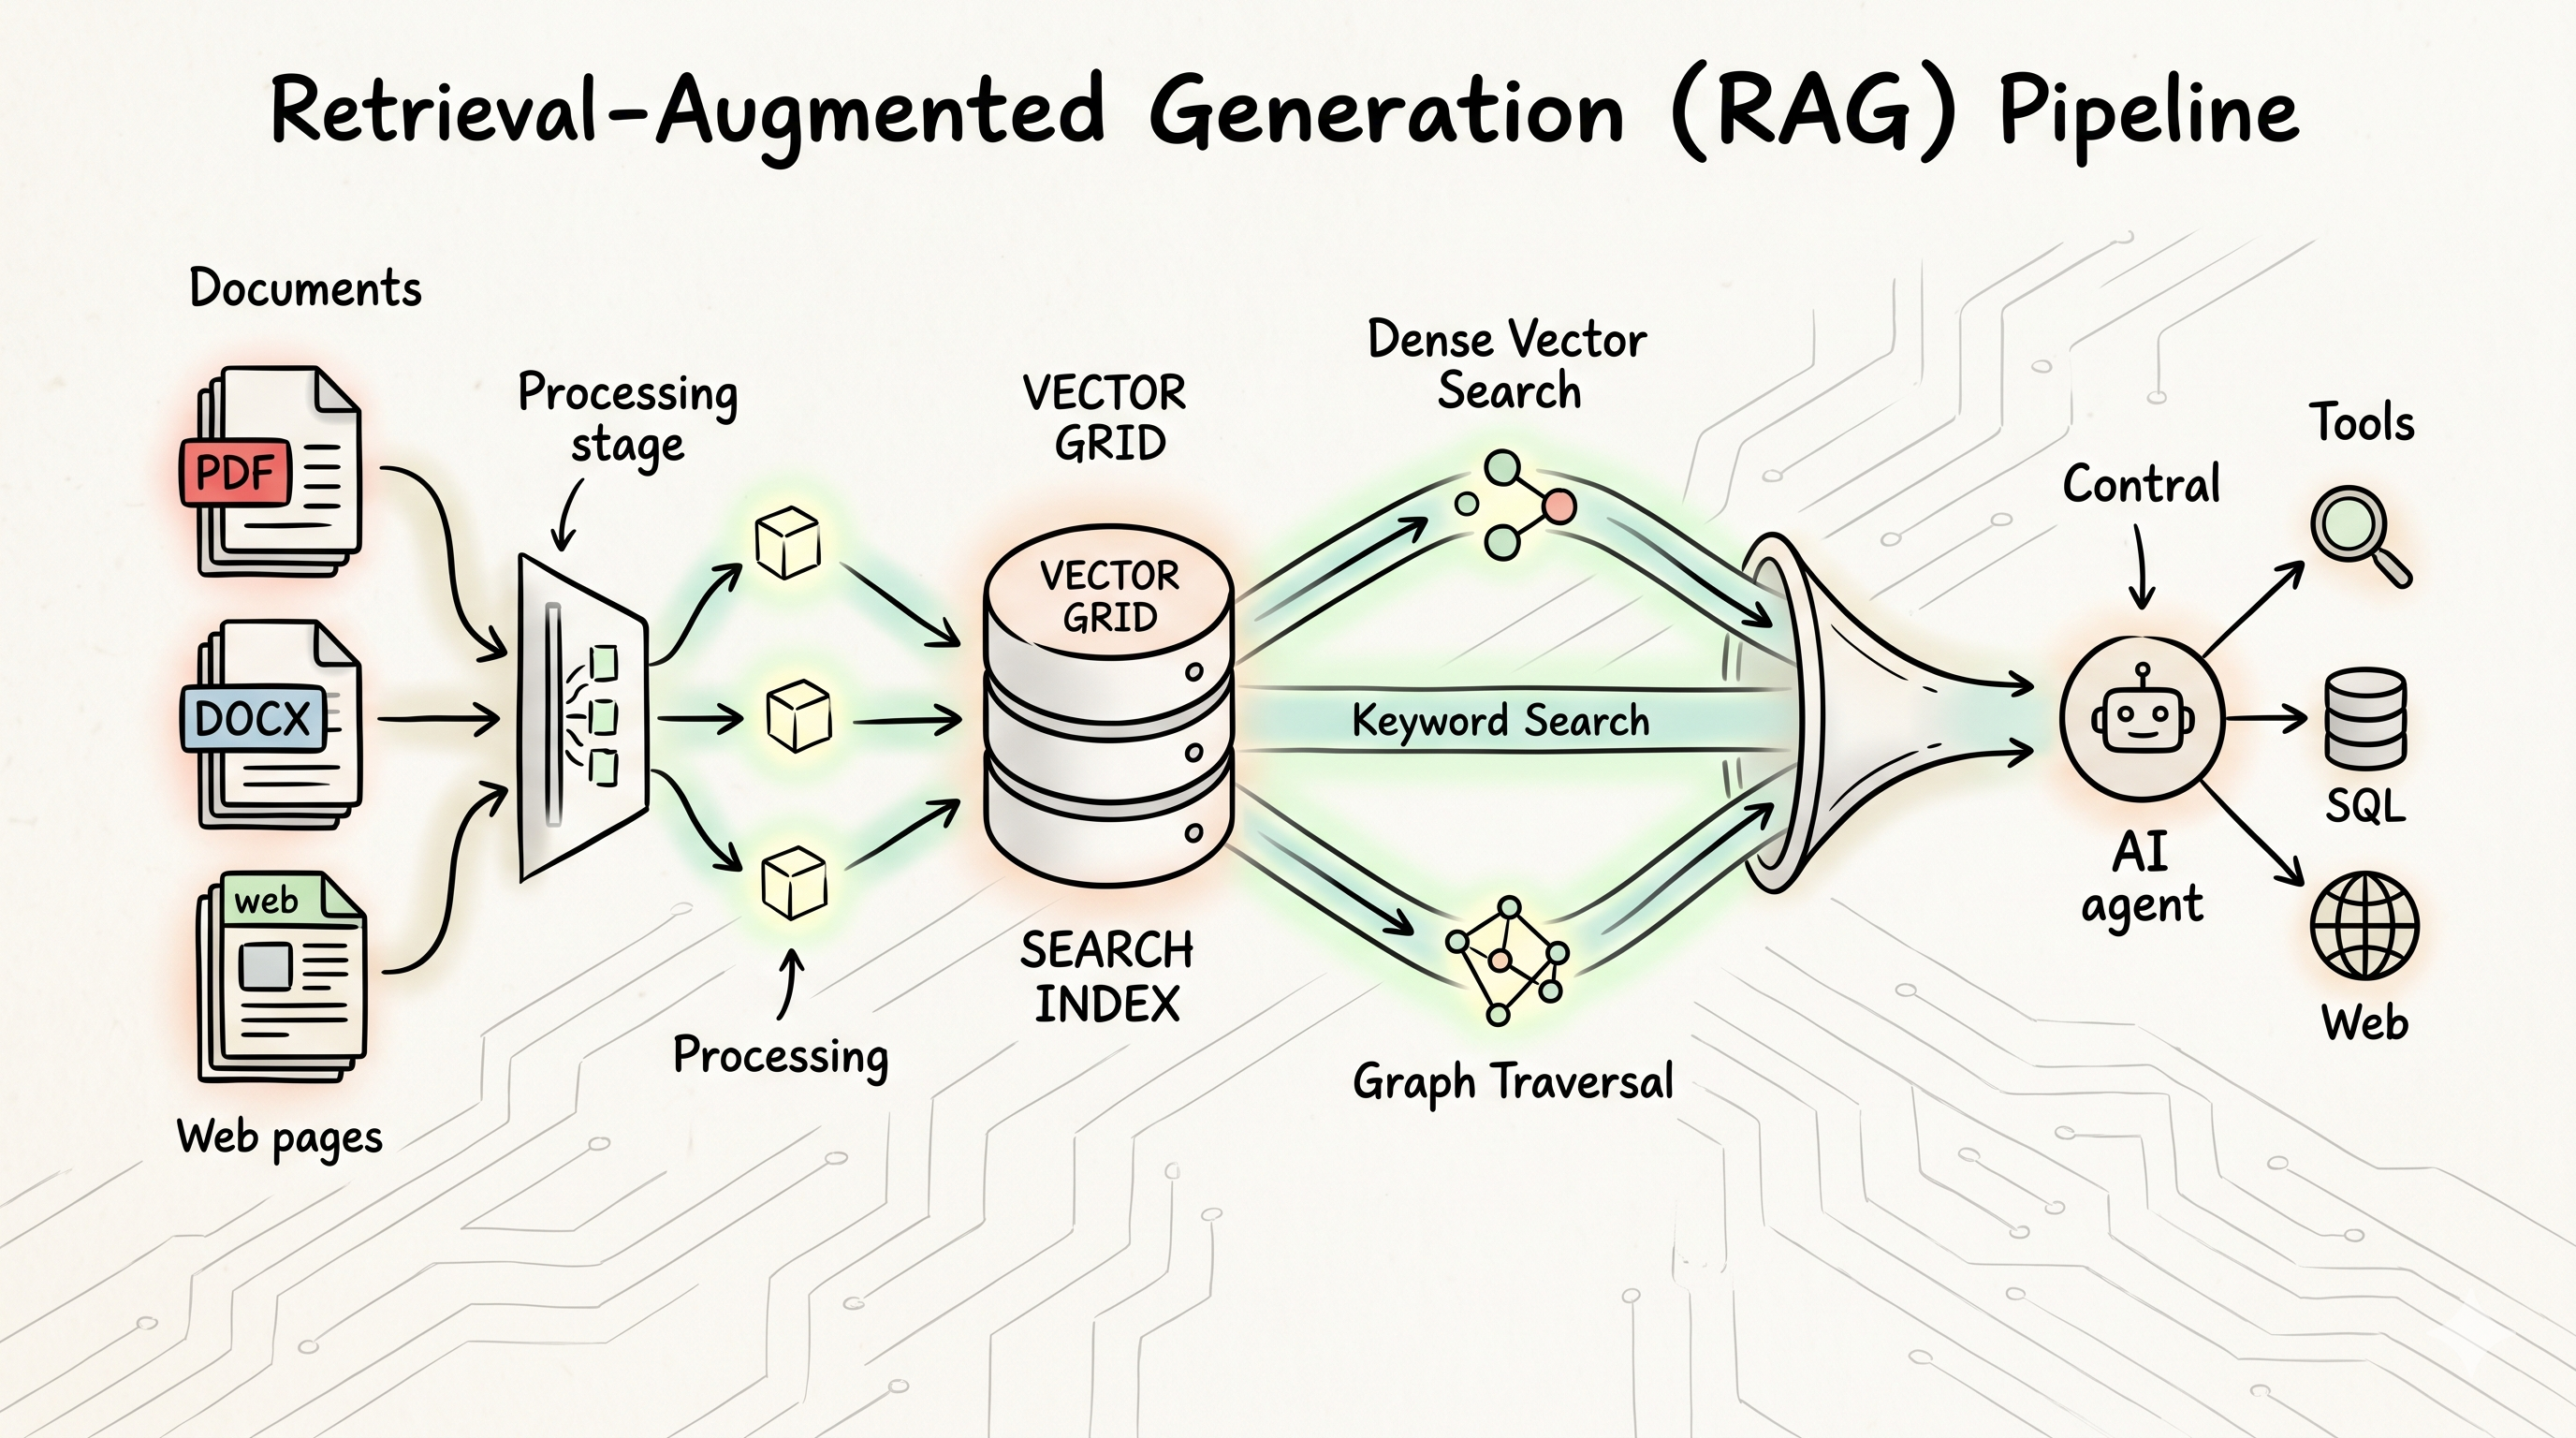
This guide covers the entire pipeline: from ingesting a raw PDF to deploying an agent that queries vector stores, SQL databases, knowledge graphs, and pre-computed summaries — and knows which one to use for each question.